Product guidance
Beyond Validation: Building a Unified Data Foundation for AI-Ready Customer Identity
Learn how customer data infrastructure for identity verification helps address Agent Amnesia and prepares contact datasets for automated AI workflows.
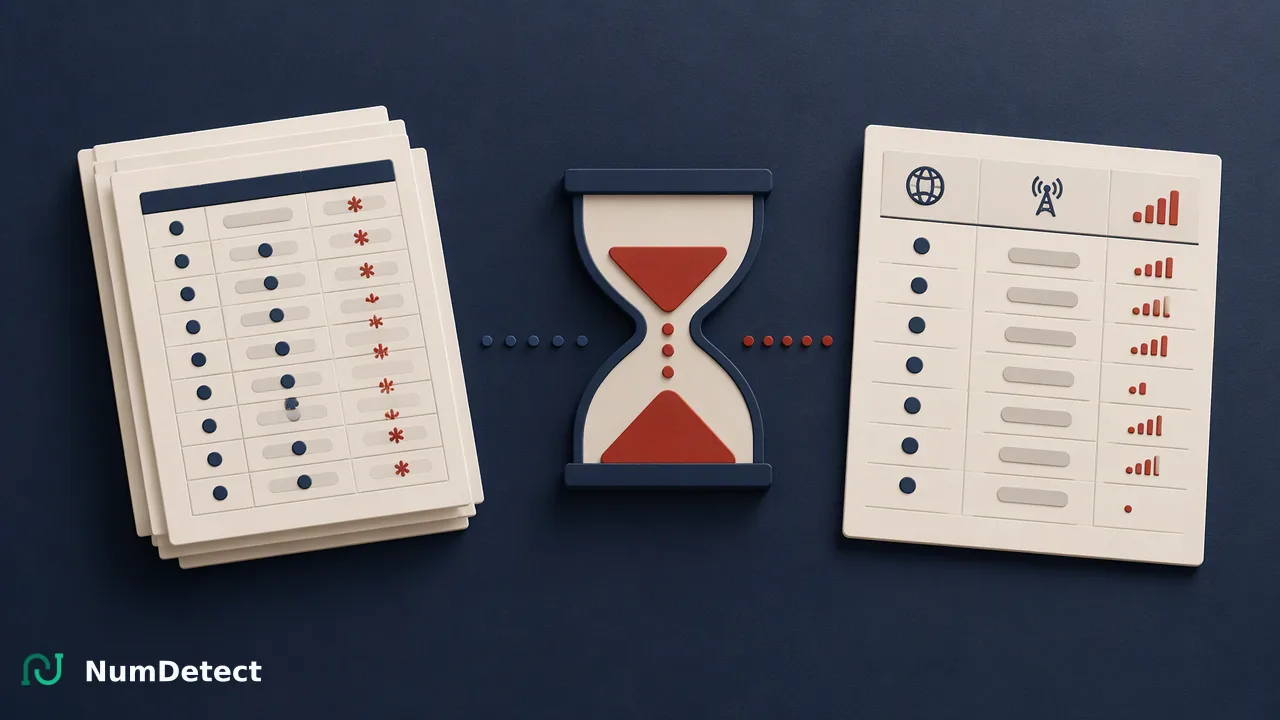
Discover why AI agents fail without a unified data foundation, how Agent Amnesia impacts operations, and how asynchronous bulk phone data hygiene supports reliable customer workflows.
Building an effective customer data infrastructure for identity verification requires organizations to clean, normalize, and verify large contact datasets before feeding them into automated systems. When artificial intelligence agents operate on fragmented or outdated records, they encounter Agent Amnesia, repeatedly losing interaction context and driving up operational overhead. Modern data infrastructure tackles this challenge by decoupling heavy verification pipelines from conversational runtimes. Through asynchronous bulk list hygiene, teams evaluate activation signals, carrier attributes, and activity signals across entire directories. This structured preparation helps organizations maintain contextual continuity, flag stale contact records, and support reliable automated workflows without introducing real-time operational bottlenecks.
The AI Paradox: Smarter Tools, Fragmented Experiences
Modern enterprises deploy conversational agents to streamline interactions, yet sophisticated tools often fail when backend data remains fragmented across disconnected silos. When automated systems query disparate databases that lack unified identifiers, they suffer from Agent Amnesia—a failure state where an automated agent cannot connect current interactions with historical records. Instead of delivering cohesive assistance, disconnected systems force users to repeat basic information or misdirect outreach entirely. As organizations scale autonomous workflows, intelligence depends heavily on data integrity. A reliable customer data infrastructure for identity verification bridges these gaps by anchoring customer profiles to verified communication signals. By validating contact records before systems ingest them, organizations establish continuous context across touchpoints, helping automated engines reference consistent, up-to-date attributes rather than guessing against outdated directory entries.
The Cost of Incomplete Identity Data
Operating automated workflows against unverified datasets introduces substantial friction and resource waste. Incomplete or invalid phone numbers lead to failed notifications, routing errors, and wasted processing cycles across automated communication queues. When records contain deactivated numbers or improper regional assignments, automated tools expend computational budget attempting outreach that cannot succeed. Beyond messaging overhead, disconnected datasets degrade customer trust. Forcing users to re-authenticate or re-explain context during automated sessions creates friction that diminishes the value of digital automation. Furthermore, internal teams lose visibility when multiple departments maintain contradictory contact attributes for the same user. Without systematic verification, CRM records accumulate invalid entries over time. Establishing proactive data review pipelines helps teams identify invalid entries early, supporting cleaner databases, reducing downstream transmission costs, and preserving customer confidence during automated engagements.
Building a Unified Data Foundation
Transitioning from static directories to an AI-ready foundation requires scalable verification mechanisms designed for broad list processing. Rather than attempting inline checks during customer-facing interactions, high-volume operations benefit from an asynchronous file-task architecture. Platforms like NumDetect provide asynchronous bulk phone-number insight workflows that handle large-scale directory hygiene independently of active agent runtimes. Teams submit datasets containing 500 to 500,000 valid phone numbers using a standard TXT or CSV file alongside a designated ISO country code via POST /api/v1/bulk-tasks. Because these bulk tasks run asynchronously, organizations avoid latency spikes in operational tools while processing large datasets. Status checks via GET /api/v1/bulk-tasks/{id} report processing progress through clear public states: processing, success, and failed. Note that China mainland numbers are not supported in this bulk workflow. This decoupled infrastructure ensures CRM databases receive regular, structured updates without impacting runtime agent responsiveness.
Operationalizing Data Hygiene for AI Readiness
Preparing contact lists for autonomous workflows involves evaluating multiple independent signals rather than relying on basic format validation alone. NumDetect offers specialized signals that help teams categorize records effectively:
- Global Carrier Detection: Delivers carrier context to inform routing decisions and segmentation, functioning as a network attribute review rather than a subscriber lookup.
- Number Activity: Returns an activity signal useful for audience ranking and segmentation, without reporting specific timestamps or frequency metrics.
- High-Value Users & E-commerce Active: Offer contextual signals reflecting network attributes and e-commerce engagement, serving as decision-support indicators rather than financial or transaction records.
Applying these distinct signals asynchronously supports technical teams in prioritizing responsive contacts, structuring regional routing, and aiding AI agent efficiency.
FAQ
Why does AI-driven customer engagement require a unified data foundation?
AI systems require accurate underlying records to maintain contextual continuity across multiple customer touchpoints. Operating on fragmented or unverified data causes Agent Amnesia, where agents lose context, prompt customers for redundant data, or trigger undeliverable communications. Integrating a verified customer data infrastructure for identity verification helps ensure systems reference clean, active identifiers, which helps reduce operational waste and supports smoother automated interactions across channels.
How does asynchronous bulk processing improve data quality for AI?
Asynchronous bulk processing helps teams review and clean extensive contact lists—ranging from 500 to 500,000 numbers per task—without overloading live conversational systems. By submitting structured files via API endpoints and checking job statuses asynchronously, organizations enrich CRMs with activation and carrier signals in scheduled runs. This background preparation provides reliable data readiness for automated workflows while avoiding latency during live customer conversations.
What is Agent Amnesia and how can organizations address it?
Agent Amnesia describes an AI system's inability to retain context across customer sessions due to fragmented or siloed backend data. Organizations address this by implementing unified data hygiene practices. Regularly validating phone lists, confirming activation signals, and enriching records with carrier context helps ensure automated agents access synchronized customer profiles, supporting ongoing continuity and reducing repetitive, disjointed interactions.
Learn More
Choose the product information that fits the next step in your workflow.